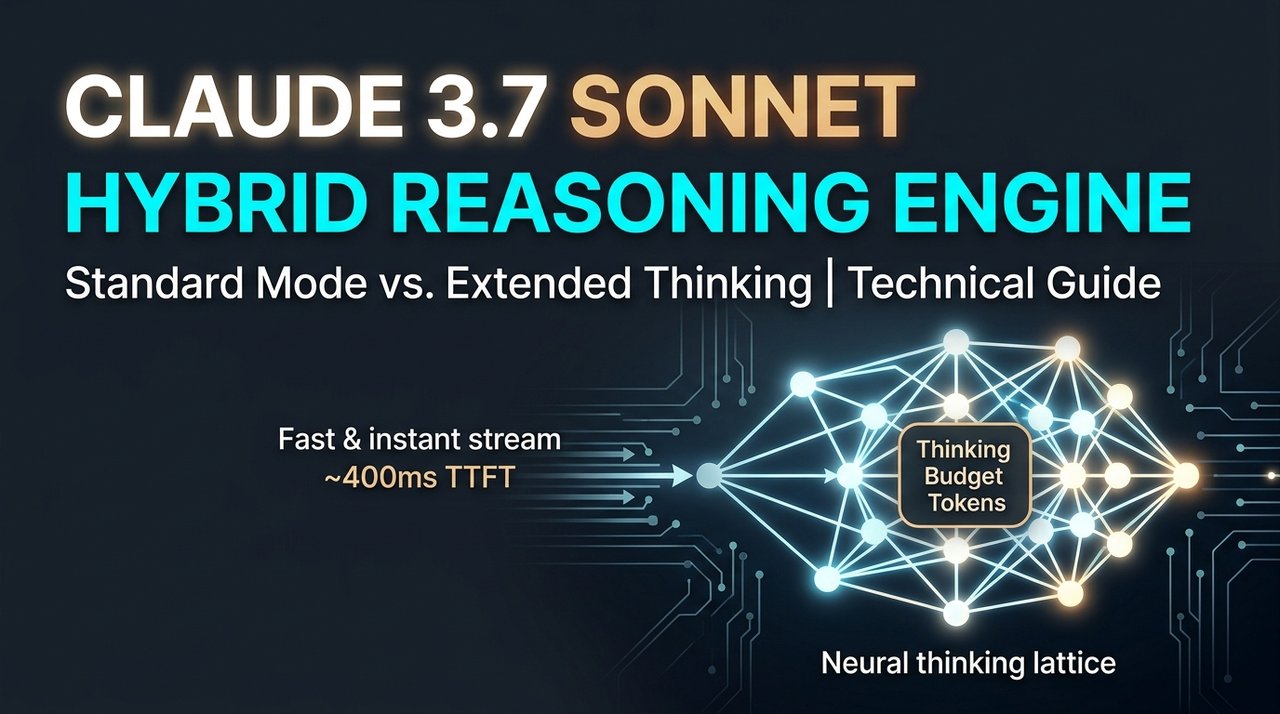
Last week Anthropic rolled out Claude 3.7 Sonnet, their first hybrid reasoning model. Unlike OpenAI's o1 and o3-mini which force extended thinking on every prompt, Claude 3.7 lets you control the reasoning budget directly or turn it off entirely.
Amir and I immediately plugged it into our production evaluation benchmarks. We ran 250 test queries across our codebase, ranging from simple database schema migrations to complex asynchronous race conditions.
The results surprised us. Turning on maximum thinking budget did not make every answer better. On standard CRUD endpoints, it added 14 seconds of latency and tripled token costs for zero noticeable quality gain. But on a thorny multi-tenant WebSocket race condition that had baffled us for two days, Claude 3.7 with a 16k thinking budget spotted the lock contention on its first try.
Here is what we learned about configuring hybrid reasoning in production, when to set a thinking budget, and how to prevent runaway API bills.
What Makes Hybrid Reasoning Different
Previous frontier models forced an all-or-nothing choice. You either picked a fast standard model (Claude 3.5 Sonnet, GPT-4o) with low latency, or an expensive reasoning model (o1) that spent 20 to 45 seconds thinking before returning a single token.
Claude 3.7 Sonnet combines both behaviors in a single endpoint using the thinking parameter:
- Standard Mode (
thinking: disabled): Operates as a fast, high-throughput model. TTFT (Time-To-First-Token) is around 400ms. Perfect for text summarization, straightforward code generation, customer support triage, and JSON extraction. - Extended Thinking Mode (
thinking: { type: "enabled", budget_tokens: N }): The model outputs an internal<thinking>block before generating its visible answer. You dictate the exact ceiling of tokens it is allowed to spend on internal deliberation.
API Request
    │
    ├── [thinking: disabled] ──────────► Immediate Token Streaming (~400ms TTFT)
    │
    └── [thinking: budget_tokens=4000] ─► Thinking Phase (<thinking>...</thinking>)
                                                 │
                                                 ▼ Visible Response Tokens
Python Implementation and Budget Tuning
Here is how we integrate Claude 3.7 Sonnet into our backend worker using the Anthropic Python SDK:
# claude_hybrid_client.py
import os
from typing import Optional
from anthropic import Anthropic

client = Anthropic(api_key=os.environ.get("ANTHROPIC_API_KEY"))

def query_claude(
    prompt: str,
    system_prompt: str,
    thinking_budget: Optional[int] = None
) -> dict:
    messages = [{"role": "user", "content": prompt}]

    # Configure thinking parameter dynamically
    kwargs = {
        "model": "claude-3-7-sonnet-20250219",
        "max_tokens": 8192,
        "system": system_prompt,
        "messages": messages,
    }

    if thinking_budget and thinking_budget >= 1024:
        kwargs["thinking"] = {
            "type": "enabled",
            "budget_tokens": thinking_budget
        }
        # max_tokens must be greater than thinking budget
        kwargs["max_tokens"] = thinking_budget + 4096

    response = client.messages.create(**kwargs)

    thinking_content = ""
    response_text = ""

    for block in response.content:
        if block.type == "thinking":
            thinking_content = block.thinking
        elif block.type == "text":
            response_text = block.text

    return {
        "thinking": thinking_content,
        "response": response_text,
        "usage": {
            "input_tokens": response.usage.input_tokens,
            "output_tokens": response.usage.output_tokens,
        }
    }
Important Budget Rules
- Anthropic requires a minimum budget of 1,024 tokens if thinking is enabled. Setting
budget_tokens: 500throws a validation error. max_tokensmust always be strictly greater thanbudget_tokens. If you setbudget_tokens: 4000, setmax_tokens: 8000to leave room for the final answer.- Tokens spent inside
<thinking>count as standard output tokens on your monthly bill.
Benchmark Comparison: Standard vs Extended
Amir and I tested 4 real-world engineering tasks across both modes to find the sweet spot:
| Engineering Task | Standard Mode (No Thinking) | Extended Mode (4,000 Budget) | Winner & Rationale |
|---|---|---|---|
| REST API boilerplate generation | 1.8s latency, 420 tokens | 12.4s latency, 2,890 tokens | Standard Mode: Zero difference in output quality; 6x faster. |
| Markdown documentation cleanup | 1.2s latency, 310 tokens | 9.8s latency, 1,940 tokens | Standard Mode: Reasoning adds zero value to copy editing. |
| Cryptographic signature verification bug | Failed (hallucinated nonce validation) | Succeeded (identified replay attack vector) | Extended Mode: Traced contract execution paths step-by-step. |
| Distributed Redis lock race condition | Proposed flawed SETNX without lease renewal | Implemented Redlock algorithm with drift calculation | Extended Mode: Caught edge cases during node restarts. |
The takeaway is clear: use Standard Mode for high-frequency user-facing interactions. Reserve Extended Thinking for complex system architecture, audit pipelines, and asynchronous debugging.
Prompt Engineering for Thinking Mode
When you turn on thinking mode, traditional prompt engineering tricks change:
What to Stop Doing
- Stop telling the model to "think step by step": Claude 3.7 already does this natively inside the thinking block. Adding chain-of-thought instructions wastes prompt tokens.
- Stop adding artificial constraints to force brevity: Let the model deliberate freely in thinking, but specify output formatting clearly for the visible text.
Effective System Prompt Template
# system_prompt.yaml
system_prompt: |
  You are a staff backend infrastructure architect.

  When thinking mode is enabled:
  - Use your internal reasoning to map edge cases, failure domains, and concurrent race conditions.
  - Stress-test your assumptions before drafting the final code.

  In your final visible response:
  - Do not summarize your internal thoughts.
  - Provide production-ready, clean code with explanatory inline comments.
  - Highlight the primary architectural trade-offs explicitly.
Architectural Decision Matrix
To help our team route prompts automatically, we built this simple routing rule in our API gateway:
# router.py
def resolve_thinking_budget(task_type: str, complexity_score: int) -> Optional[int]:
    if task_type in ["copywriting", "sql_query", "json_format", "crud_scaffold"]:
        return None  # Standard mode

    if task_type in ["code_review", "security_audit", "algorithm_optimization"]:
        if complexity_score > 7:
            return 8192  # Deep architectural reasoning
        return 2048      # Moderate algorithmic reasoning

    return None
Hybrid reasoning gives developers full control over the latency-cost-intelligence trade-off. By routing simple queries to standard mode and reserving thinking tokens for genuine algorithmic complexity, you get frontier reasoning power without breaking your latency budget or cloud invoice.



Comments
Comments are reviewed before appearing publicly.
No comments yet — be the first.