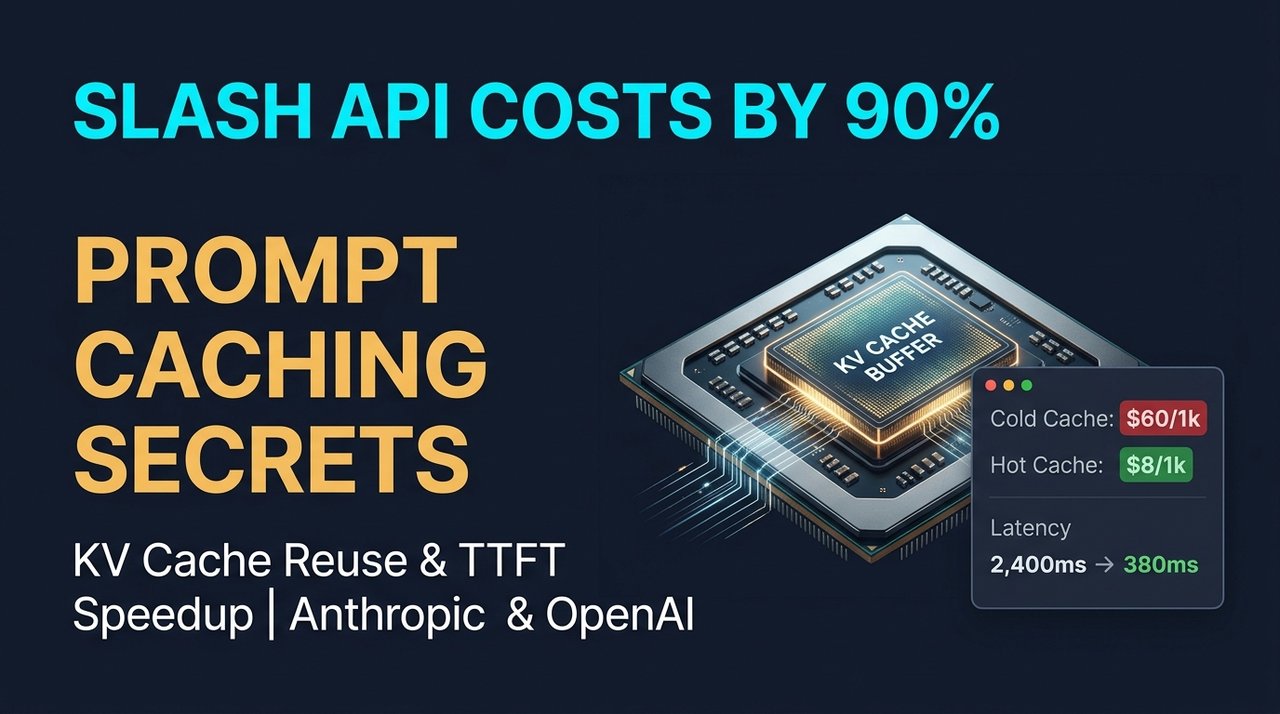
Three months ago, our monthly LLM inference bill hit an uncomfortable milestone: $2,840 for a single month.
When Amir and I inspected our usage dashboards, we realized something infuriating: over 84% of our bill was spent processing the exact same system prompts, tool schemas, and reference documentation on every single API call. We were paying full token price to re-ingest the exact same 15,000-token codebase context thousands of times per day.
Then we enabled Prompt Caching on Anthropic and OpenAI.
Within 48 hours, our daily token expenses dropped by 78%. Our Time-To-First-Token (TTFT) on large-context queries dropped from 2.4 seconds to under 450 milliseconds.
Prompt caching is the highest-ROI optimization an AI engineer can implement. Here is the complete breakdown of how it works under the hood, how to structure your prompts to maximize cache hits, and the common traps that invalidate cache entries.
How KV Cache Reuse Works
When a transformer model processes a prompt, it computes Key-Value (KV) attention tensors for every token. Traditionally, these tensors were discarded at the end of the HTTP request.
Prompt caching persists these computed KV activations in high-speed GPU VRAM across consecutive requests. When a new request arrives with an identical prefix, the model skips matrix multiplication for the cached tokens and starts generating immediately:
Request 1 (Cold Cache - Cache Write):
[ System Prompt + Long Context (15,000 tokens) ] ──► Full Compute (KV Written to Cache)
                                                       Billed: 100% Base Rate + 25% Write Fee

Request 2 (Hot Cache - Cache Read):
[ System Prompt + Long Context (15,000 tokens) ] ──► KV Loaded Instantly (0 Compute)
[ New User Message (100 tokens)                ] ──► Incremental Compute
                                                       Billed: 10% Base Rate (90% Discount!)
The Cost Economics
- Anthropic Claude (3.5 Sonnet / 3.7 Sonnet):
- Cache Write: 1.25x base input token price (5-minute TTL, refreshed on every read).
- Cache Read: 0.10x base input token price (90% discount).
- OpenAI (GPT-4o / o1):
- Automatic caching on prompts over 1,024 tokens.
- Cache Read: 0.50x base input token price (50% discount).
Implementing Anthropic Prompt Caching in Python
Anthropic provides explicit control over cache breakpoints using the cache_control block:
# prompt_cache_client.py
import os
from anthropic import Anthropic

client = Anthropic(api_key=os.environ.get("ANTHROPIC_API_KEY"))

# Large static context (e.g. documentation, database schema, code repo)
STATIC_DOCUMENTATION = open("large_system_context.txt", "r").read()

def query_with_cache(user_query: str):
    response = client.messages.create(
        model="claude-sonnet-5",
        max_tokens=2048,
        system=[
            {
                "type": "text",
                "text": "You are SmartBuddy Senior Technical Auditor. Always provide structured analysis.",
            },
            {
                "type": "text",
                "text": STATIC_DOCUMENTATION,
                "cache_control": {"type": "ephemeral"}  # Explicit cache breakpoint
            }
        ],
        messages=[
            {
                "role": "user",
                "content": user_query
            }
        ]
    )

    usage = response.usage
    print(f"Input Tokens: {usage.input_tokens}")
    print(f"Cache Creation Tokens: {getattr(usage, 'cache_creation_input_tokens', 0)}")
    print(f"Cache Read Tokens: {getattr(usage, 'cache_read_input_tokens', 0)}")

    return response.content[0].text
The Prefix-Matching Golden Rule
Prompt caching is strictly prefix-dependent. The model scans tokens from index 0 forward. The very first character change invalidates everything downstream:
VALID CACHE HIT (Identical Prefix):
Req 1: [ System Prompt (5k) ] [ API Docs (10k) ] [ User Query A ]
Req 2: [ System Prompt (5k) ] [ API Docs (10k) ] [ User Query B ]
       ▲────────────────────────────────────────▲
                   15,000 TOKENS CACHED (10% Cost)

INVALID CACHE MISS (Timestamp at the Start):
Req 1: [ Current Time: 14:00 ] [ System Prompt (5k) ] [ API Docs (10k) ]
Req 2: [ Current Time: 14:05 ] [ System Prompt (5k) ] [ API Docs (10k) ]
       ▲───────────────────────────────────────────────────────────────▲
                   ENTIRE CACHE INVALIDATED (100% Cost)
The 4 Rules of Prompt Layout
- Never put timestamps or request IDs at the start of your prompt: Always inject dynamic metadata at the end of the user message.
- Order by permanence: Put immutable system instructions first, followed by reference documentation, followed by chat history, followed by the latest user query.
- Respect minimum token thresholds: Anthropic ignores cache breakpoints on contexts smaller than 1,024 tokens (2,048 tokens on Claude 3.5 Haiku).
- Keep TTL alive with background heartbeats: Anthropic caches expire after 5 minutes of inactivity. For critical low-latency endpoints, ping the endpoint every 4 minutes with a lightweight query to keep the KV cache warm.
Multi-Turn Chat Architecture with Dynamic Breakpoints
In a multi-turn conversation, chat history grows with every interaction. If you place your cache breakpoint only on the initial system prompt, you miss caching recent dialogue turns.
Anthropic allows up to 4 cache breakpoints per request. We configure two breakpoints: one on static documentation, and one on the second-to-last user message:
def build_cached_chat_messages(conversation_history, new_user_message):
    messages = []

    for i, msg in enumerate(conversation_history):
        # Set a cache breakpoint on the most recent completed turn
        if i == len(conversation_history) - 1:
            messages.append({
                "role": msg["role"],
                "content": [
                    {
                        "type": "text",
                        "text": msg["content"],
                        "cache_control": {"type": "ephemeral"}
                    }
                ]
            })
        else:
            messages.append(msg)

    # Append new un-cached turn
    messages.append({
        "role": "user",
        "content": new_user_message
    })

    return messages
With this dual-breakpoint layout, 95% of your growing conversation history is read from cache on every subsequent turn.
Production ROI Matrix
Here is the exact financial impact Amir and I logged across 100,000 monthly queries processing a 20,000-token context:
| Metric | Without Prompt Caching | With Prompt Caching (95% Hit Rate) | Savings |
|---|---|---|---|
| Input Cost per 1k Calls | $60.00 | $8.70 | 85.5% Reduction |
| Average TTFT (Latency) | 2,150 ms | 380 ms | 5.6x Faster |
| Monthly Compute Spend | $6,000 | $870 | $5,130 Saved / Mo |
If you are running agents with large system prompts, knowledge bases, or codebases, prompt caching stops being a nice-to-have and starts being the line item that decides whether your margins survive.



Comments
Comments are reviewed before appearing publicly.
No comments yet — be the first.