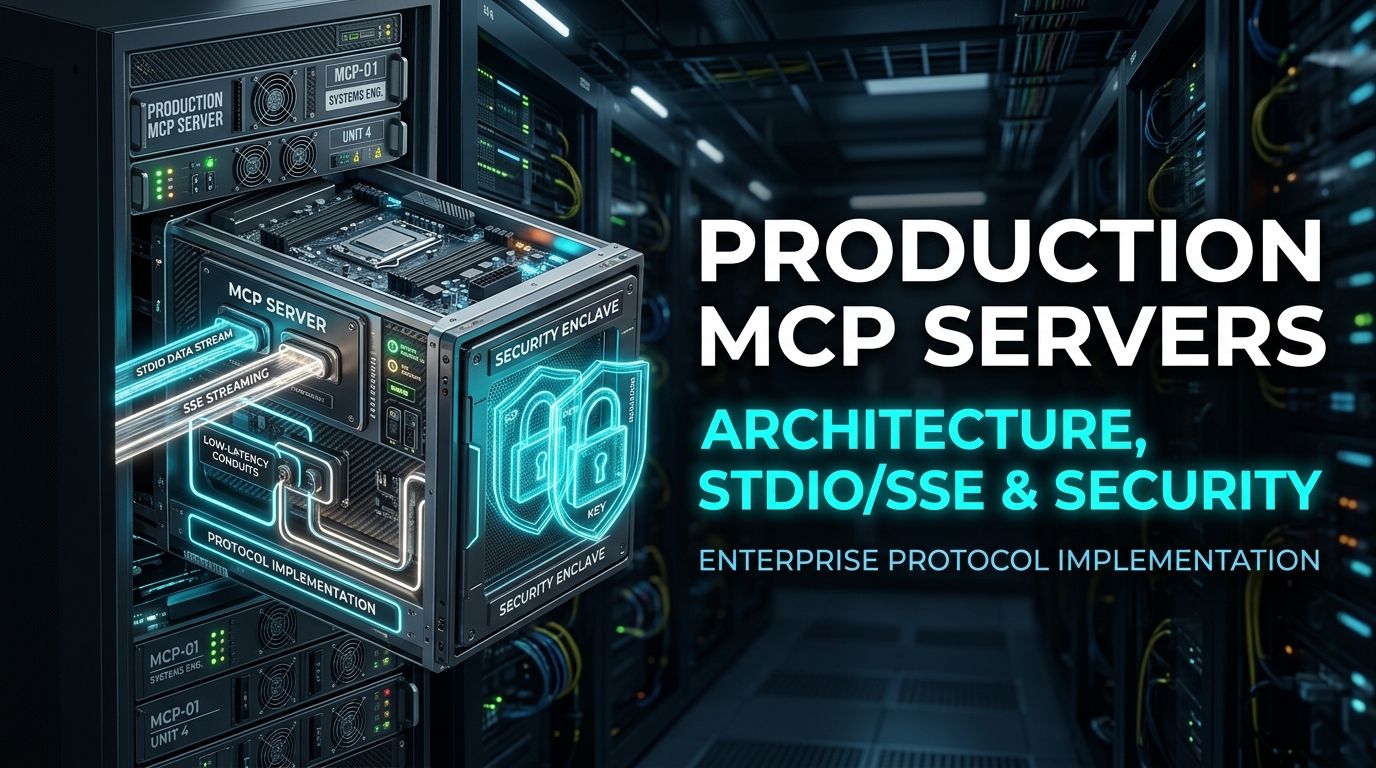
Before the Model Context Protocol, connecting an agent to Postgres, GitHub, and Slack meant three separate function-calling implementations, each tied to whichever LLM provider you happened to be using. Change providers, or even update one integration, and something else quietly broke.
MCP fixes that by putting a real protocol between the agent and the tool layer, instead of a pile of provider-specific glue code.
[Claude Desktop / Cursor / Antigravity]
                │
                │  JSON-RPC 2.0, over Stdio or SSE
                ▼
       [Your MCP Server]
                │
     ┌──────────┼──────────┐
     ▼          ▼          ▼
[Postgres]  [Stripe]   [Local files]
Three Things an MCP Server Actually Exposes
Tools do things. Creating a GitHub issue, charging a Stripe invoice, anything with a side effect. These enforce type safety through JSON Schema so the agent can't pass garbage into a function that mutates something real.
Resources are read-only. An application log stream, an OpenAPI spec, anything the agent needs to see but shouldn't be able to change through this interface.
Prompts are reusable templates. Pre-packaged instructions that guide how the agent should approach a specific kind of task, so you're not rewriting the same reasoning scaffold into every call.
Here's a minimal, actually-runnable server:
from fastmcp import FastMCP
from pydantic import BaseModel, Field

mcp = FastMCP("Database Audit Server")

class QueryParams(BaseModel):
    table_name: str = Field(..., description="Target database table name")
    limit: int = Field(default=10, le=100, description="Maximum rows to inspect")

@mcp.tool()
def inspect_table_health(params: QueryParams) -> dict:
    """Audit table fragmentation and index coverage safely."""
    sanitized_table = sanitize_identifier(params.table_name)
    return run_safe_query(
        f"SELECT * FROM pg_stat_user_tables WHERE relname = :table",
        {"table": sanitized_table},
    )

if __name__ == "__main__":
    mcp.run(transport="stdio")
Notice the limit field caps at 100 and the table name gets sanitized before it touches a query. That's not defensive boilerplate, it's the difference between a tool an agent can use safely and one that lets a bad prompt turn into a database problem.
Picking Stdio or SSE Isn't a Style Choice
| Stdio | SSE | |
|---|---|---|
| Where it runs | Local subprocess | Remote server, container |
| Auth | OS file permissions | Bearer token or OAuth |
| Latency | Basically none, it's IPC | Standard HTTP overhead |
| Use it for | A local CLI tool or IDE plugin | Multi-tenant SaaS, a shared team agent |
If you're building a personal tool that only runs on your own machine, Stdio is simpler and faster. The moment more than one person or one deployment needs to hit the same server, you're in SSE territory, and the auth model changes with it.
The Security Step People Skip
Every argument an agent passes into a tool needs schema validation before it touches anything real, a database query, a shell command, a file path. Skip this and you're one cleverly-worded prompt away from an agent passing a raw string straight into a SQL query. Add rate limiting per client and scope database roles to read-only where you can. A tool that only needs to read table stats shouldn't be running under a role that can also drop tables.
Frequently Asked Questions
Can one MCP server call another MCP server?
Yes. You can chain them in a gateway configuration where a central orchestrator routes requests to specialized microservice servers behind it.
What's the actual attack surface for prompt injection here?
The tool arguments themselves. Strict schema validation, read-only database roles wherever possible, and requiring a human approval gate for high-impact actions close most of the realistic attack paths.
Do I need SSE if I'm only building this for myself?
No. If it's just you, running locally, Stdio is simpler, faster, and has one less thing to secure. Move to SSE when someone else, or another deployment, needs to reach the same server.



Comments
Comments are reviewed before appearing publicly.
No comments yet — be the first.